 Ryan Zhang's Blog

Is InfiniBand’s “Infinite Bandwidth” Really Infinite? 🤔
Translation Notice
This article was originally written in Chinese and translated into English with the assistance of AI. The translation has been reviewed and edited for clarity, accuracy, and readability. Please refer to the original source where necessary, especially for technical terms, commands, configuration details, and proper nouns.
Introduction
Recently, the “DataCenter” my friends and I built (ahem, really just a few servers) needed a storage upgrade. Our goal was clear: build an all-flash and a hybrid-flash centralized storage system to serve the virtualization nodes and create something with an “enterprise” feel. The easiest solution would have been to spend money—for example, Huawei’s OceanStor Dorado. Just pay and you are done. But this setup is mainly for personal tinkering and occasional testing,
Open source is our true destination!
Why open source? Don’t ask—the budget is limited (qiong)! #Insert doge here
⚡️ Theoretical Speed of an All-Flash Array
Assuming each drive reads and writes at about 500 MB/s (roughly 5 Gbps), a six-drive RAID 5 array would theoretically provide:
- Write: 500 MB/s * (6-1) ≈ 2.5 GB/s (parity overhead may prevent reaching this in practice)
- Read: 550 MB/s * 6 ≈ 3.3 GB/s (far above 10 Gbps)
RAID 0 would be unbelievably fast, but the retired compute node now used as a storage server has a RAID controller limited to 12 Gbps. Going beyond that would require a direct PCIe path. We therefore set 10 Gbps as the network requirement.
Transmission Medium
10 Gbps media is now widely available: fiber, DAC cables, and even good Ethernet cables over short distances can handle it. We had collected some used enterprise hardware, including 40 Gbps Mellanox CX341 cards. Initially, we planned direct P2P connections between storage and compute nodes. But after the upgrade we had three compute nodes, so direct connections would require many 40 Gbps NICs. The essence of open source is:
saving money!
That was clearly uneconomical, so we bought a barely used Cisco Nexus 3064PQ-10GX. It has 48 10G ports and four 40G ports, which can also be split into 4×10G. Using a switch solved the multi-node connection problem perfectly.
Storage System
Consumer and lightweight NAS platforms such as Synology and Feiniu struggled in this speed-focused environment. We ultimately chose TrueNAS: open source, free, friendly to all-flash and hybrid-flash storage, and backed by the powerful ZFS filesystem.
TrueNas
Network Architecture
Compute nodes:
- Connect to the switch through 10 Gbps NICs. Storage server:
- Connect to the switch through 40 Gbps NICs.
That gave us a dedicated, high-speed storage network! Then another problem appeared: our virtualization nodes run 50 or 60 VMs. If they all read and write storage simultaneously, the 10 Gbps aggregate bandwidth could be overwhelmed. The storage server’s low-power CPU might not handle the load either.
What a coincidence, right?
While we were scratching our heads, we remembered the used Mellanox NICs we had. They are excellent for RDMA (Remote Direct Memory Access), which bypasses the CPU and moves data directly between the NIC and memory, delivering high efficiency, low latency, and light CPU load.
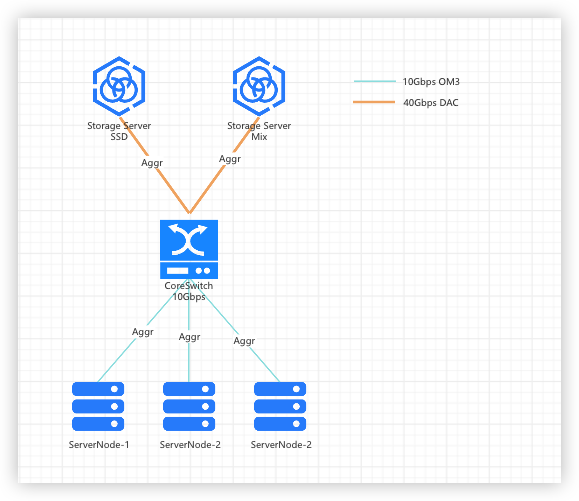
Storage network topology
P.S. This preamble got a little long… now to the main topic.
A Brief Introduction to RDMA
Before discussing RDMA (Remote Direct Memory Access), we should first introduce its foundation: InfiniBand (IB).
InfiniBand Trade Association
What is it? Simply put, it is a high-performance, low-latency networking protocol widely used in supercomputing, data centers, and AI training clusters where performance is critical. RDMA’s magic is built on it.
Search for InfiniBand and you may find it described as “infinite bandwidth.” That is an exaggeration. It has no literal physical infinity; rather, its bandwidth is enormous and its scalability exceptional, pushing beyond Ethernet’s performance ceiling.
At Supercomputing 2024, NVIDIA presented the ConnectX-8, reaching 800 Gbps per port—about 80 GB per second, enough to transfer a Blu-ray movie in roughly one second.
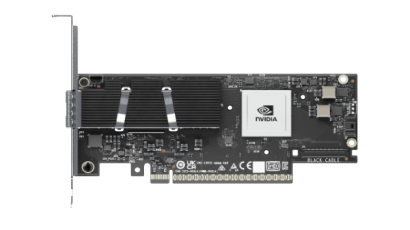
ConnectX-8 1
✅ Advantages of IB Networking
1. Extremely High Bandwidth
As mentioned above, it is extremely fast and well suited to HPC and AI training workloads that move terabytes of data back and forth.
2. Ultra-Low Latency + Zero Copy
This is its biggest difference from Ethernet:
- Supports RDMA (Remote Direct Memory Access).
- Data bypasses the CPU and operating-system kernel, moving directly from memory to memory.
- The CPU is barely involved, with latency as low as sub-microsecond levels.
- This is dramatically lower than the tens of microseconds typical of ordinary Ethernet.
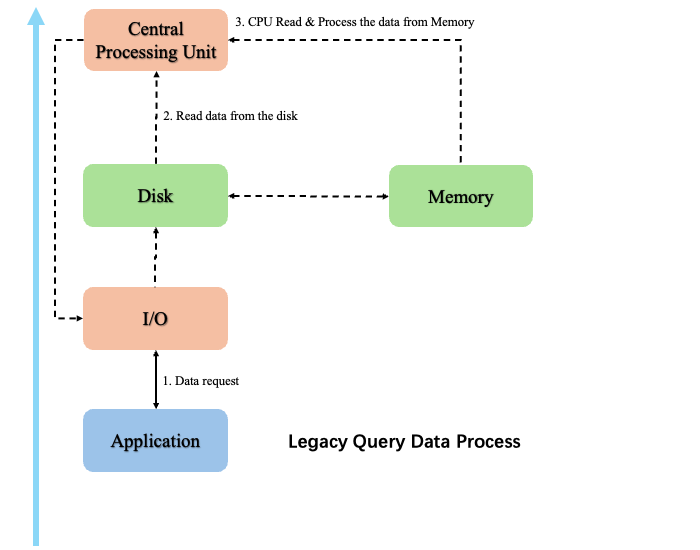
Traditional network flow
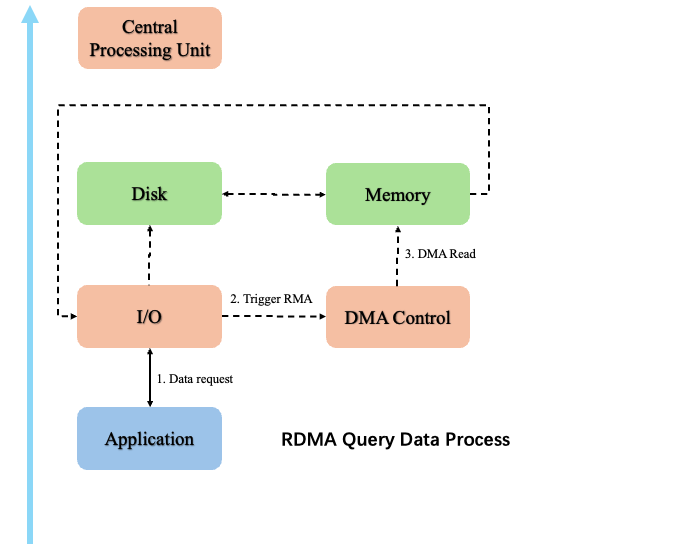
RDMA network flow
🧱 Every advantage has a downside:
1. IB is not simply a matter of buying a few cables; it is a complete closed ecosystem including:
- Dedicated IB switches
- IB HCA NICs, such as NVIDIA/Mellanox ConnectX
- Software supporting the IB protocol stack
🧾 Cost is a major barrier, especially for small and medium deployments. RoCE allows RDMA to run over traditional Ethernet and reuse high-speed Ethernet hardware, but compatible NICs and software are still required.
| Dimension | InfiniBand | iWARP (TCP-based) | RoCE (Ethernet-based) |
|---|---|---|---|
| Performance | Best | Lower (TCP overhead) | Comparable to InfiniBand |
| Cost | High | Medium | Low |
| Stability | Good | Poor | Better |
| Switch type | Dedicated IB | Ethernet | Ethernet |
Data in the table is based on Huawei support documentation2.
2. It Does Not Interoperate Directly with Traditional Ethernet
InfiniBand is a network, but it does not use the IP protocol suite. It has its own addressing, flow control, and protocol layers, which means:
- It cannot connect directly to an existing Ethernet network.
- External connectivity requires a gateway for protocol conversion, such as an IB-Ethernet gateway.
- Software support is not plug-and-play; many server applications need specific RDMA or IB API adaptations.
For hybrid deployments or environments with extensive Ethernet infrastructure, IB’s adoption barrier and operational complexity must be considered.
✍️ Final Thoughts
RDMA + InfiniBand is a classic “buy performance at any cost” solution.
As AI and cloud computing have advanced rapidly, many enterprise scenarios are quietly approaching the ceiling of traditional network architectures. IB is increasingly useful for applications requiring high bandwidth, high concurrency, and extremely low latency.
AI model training may involve hundreds of high-performance GPUs, such as NVIDIA A100 or H100 cards, working together. They cannot all fit in one machine, so computation must span nodes. If latency is too high, data transfer cannot keep up and GPU performance suffers severely; this is where IB is valuable.
In my view, IB is not suitable for every organization or project for two main reasons:
1. High Deployment Cost
Running a complete IB network can exhaust the budget on NICs and switches alone. For most organizations, traditional Ethernet and SAN switches with 10G/16G/25G networking already meet everyday storage and throughput needs.
2. Deployment and Compatibility Barriers
From hardware and software to operations, additional learning and adaptation are required, and many common services do not support it directly.
When is InfiniBand worth considering? Add IB to your shortlist if any of these scenarios apply:
- Deploying an AI training or inference cluster with many GPU nodes.
- Using distributed storage such as Ceph with latency-sensitive workloads.
- Operating a large-scale data-distribution system that requires maximum bandwidth.
🔗 References:
[1] https://nvdam.widen.net/s/pxsjzhgw6j/connectx-datasheet-connectx-8-supernic-3231505
[2] https://support.huawei.com/enterprise/zh/doc/EDOC1100203347
Support & Share
If this article helped you, please share or support!